Strata on a 12 GB gaming GPU
Radeon RX 6700 XT · Ryzen 5 3600 · 32 GB DDR4-3200 · Strata v0.1.45 HIP
Status: completed benchmark evidence. Two full quality-suite models; three supplemental speed/context references; four incompatible variants. Results observed October 17–18, 2026 UTC.
Official Strata benchmarks — unmodified upstream tool
Original tools/strata_bench.py speed measurements, three runs per configuration. Tables show medians; ranges and individual requests remain in the canonical data and original tool output. Context allocations are kept separate. A dash means that workload was not run.
| Model | Allocated tokens | Chat tok/s | TTFT seconds | 4K prompt tok/s | 16K prompt tok/s | 32K prompt tok/s | Accepted/offered drafts | Tool failures |
|---|
| Flash-Next Coder IQ1_M | 32768 | 22.4 | 1.499 | 327.1 | 342.2 | — | 1043/1722 | 0 |
| Flash-Next Coder IQ1_M | 65536 | 21.2 | 1.693 | 321.3 | 341.5 | 337.5 | 1181/1874 | 0 |
| Qwen3.6 UD-Q4_K_XL | 32768 | 33.2 | 0.667 | 814.3 | 677.5 | — | 0/0 | 0 |
| Qwen3.6 UD-Q4_K_XL | 65536 | 24.6 | 0.865 | 813.4 | 677.8 | 543.5 | 0/0 | 0 |
| Qwen3.6 UD-Q3_K_M (no MTP) | 65536 | 27.4 | 0.673 | 862.6 | 721.4 | 581.5 | 0/0 | 0 |
| Qwen3.6 UD-Q3_K_M (no MTP) | 81920 | 23.5 | 0.834 | 862.5 | 721.3 | 581.7 | 0/0 | 0 |
| Qwen3.6 UD-Q4_K_M (MTP file) | 65536 | 27.5 | 0.815 | 814.8 | 678.0 | 543.3 | 0/0 | 0 |
| Qwen3.6 UD-Q4_K_M (MTP file) | 81920 | 24.8 | 0.879 | 813.3 | 678.2 | 543.5 | 0/0 | 0 |
| Qwen3.6 UD-Q3_K_XL (no MTP) | 65536 | 26.4 | 0.706 | 861.5 | 721.0 | 581.4 | 0/0 | 0 |
| Qwen3.6 UD-Q3_K_XL (no MTP) | 81920 | 22.6 | 0.831 | 861.8 | 720.9 | 581.5 | 0/0 | 0 |
| Model | Allocated tokens | Agent tok/s | Agent TTFT seconds | Cache reuse (%) | Two-client aggregate tok/s | Two-client p95 TTFT (s) | Client errors |
|---|
| Flash-Next Coder IQ1_M | 32768 | 24.7 | 9.383 | 68.793 | — | — | — |
| Flash-Next Coder IQ1_M | 65536 | 24.5 | 9.763 | 68.488 | 15.57 | 11.432 | 0 |
| Qwen3.6 UD-Q4_K_XL | 32768 | 32.6 | 11.803 | 0.0 | — | — | — |
| Qwen3.6 UD-Q4_K_XL | 65536 | 27.7 | 11.785 | 0.0 | 22.7 | 7.054 | 0 |
| Qwen3.6 UD-Q3_K_M (no MTP) | 65536 | 29.6 | 11.018 | 0.0 | — | — | — |
| Qwen3.6 UD-Q3_K_M (no MTP) | 81920 | 26.7 | 10.997 | 0.0 | — | — | — |
| Qwen3.6 UD-Q4_K_M (MTP file) | 65536 | 29.9 | 11.723 | 0.0 | — | — | — |
| Qwen3.6 UD-Q4_K_M (MTP file) | 81920 | 26.8 | 11.723 | 0.0 | — | — | — |
| Qwen3.6 UD-Q3_K_XL (no MTP) | 65536 | 28.7 | 10.999 | 0.0 | — | — | — |
| Qwen3.6 UD-Q3_K_XL (no MTP) | 81920 | 25.8 | 11.071 | 0.0 | — | — | — |
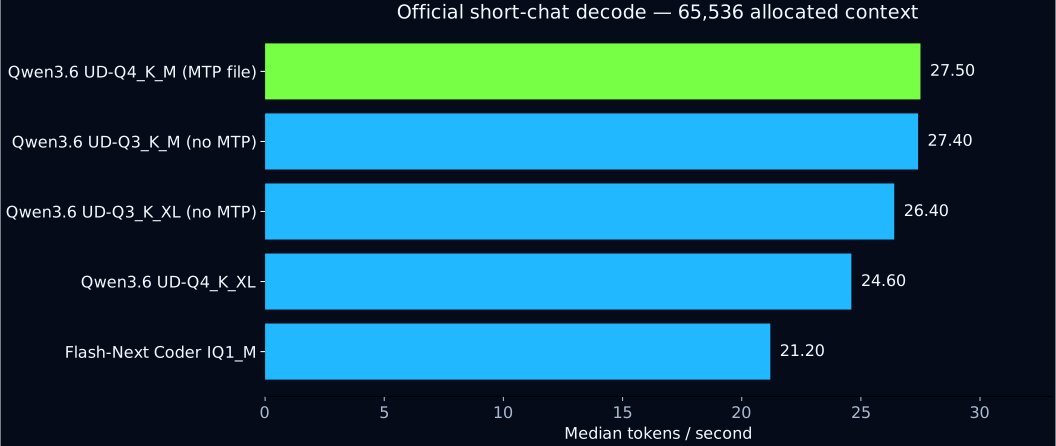
Extended tests use --long; the two primary extended tests also use --clients 2. Two-client requests queued on one engine slot. Qwen MTP requests produced zero drafts; Coder produced drafts, without an MTP on/off comparison. Q3 no-MTP compatibility copies add only zero-MTP metadata; tensor bytes are verified unchanged. These are speed measurements, not correctness scores.
Custom benchmarks — practical quality, coding and retrieval
Qwen3.6 Q4_K_XL leads the custom weighted index by 1.36 points. Coder leads HumanEval+ coding and validated context length. Supplemental quant runs have no quality scores.
| Model | Weighted index | HumanEval+ | Practical attempts | Empty practical answers |
|---|
| Flash-Next Coder IQ1_M | 95.08 | 152/164 (92.68%) | 72 | 1 |
| Qwen3.6 UD-Q4_K_XL | 96.44 | 130/164 (79.27%) | 72 | 0 |
The index is a custom v2.1 rubric: 90% applied-task categories and 10% HumanEval+. Applied tasks are 24 fixtures repeated three times, not 72 different tasks. This index is not an official Strata quality benchmark.
| Index category | Weight (%) |
|---|
| Business | 20 |
| Research | 20 |
| Knowledge | 20 |
| Agent Tools | 15 |
| Practical Sysadmin | 5 |
| Humaneval Plus | 10 |
| Executive Content | 10 |
Context: allocation versus actual recall
| Model | Highest allocation with recall | Highest retrieved prompt | Failed start contexts |
|---|
| Flash-Next Coder IQ1_M | 131072 | 125573 | — |
| Qwen3.6 UD-Q4_K_XL | 81920 | 75930 | 131072, 98304 |
| Qwen3.6 UD-Q3_K_M (no MTP) | 81920 | 75930 | 131072 |
| Qwen3.6 UD-Q4_K_M (MTP file) | 81920 | 75930 | 131072 |
| Qwen3.6 UD-Q3_K_XL (no MTP) | 81920 | 75930 | 131072 |
| Qwen3.6 UD-IQ3_S (MTP file) | — | — | 131072, 65536, 81920 |
| Qwen3.6 UD-IQ3_XXS (MTP file) | — | — | 131072, 65536, 81920 |
| Qwen3.6 UD-IQ4_XS (MTP file) | — | — | 131072, 65536 |
| Genesis-Hermes APEX Compact | — | — | 131072, 65536, 81920 |
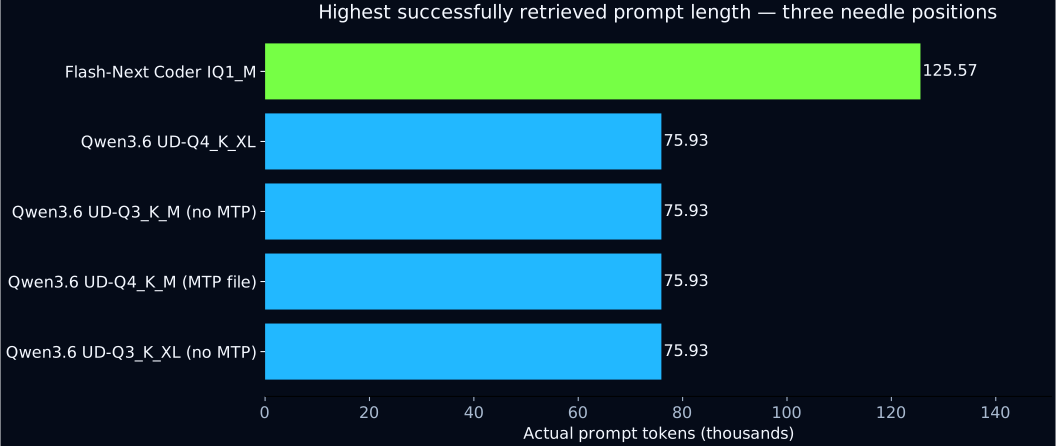
Passing three needle positions does not establish broad long-context accuracy. These are highest tested successes, not exact limits.
Dossier workload: three repetitions of the same fixture
| Model | Prompt tokens | First repetition (s) | Median wall time (s) | Cached prompt tokens by repetition |
|---|
| Flash-Next Coder IQ1_M | 57135, 57135, 57135 | 250.2572 | 90.4603 | 0, 57130, 57130 |
| Qwen3.6 UD-Q4_K_XL | 57097, 57097, 57097 | 313.9941 | 319.78 | 0, 0, 0 |
Repeated-fixture cache effects differ between models. These are observed workload times, not a controlled cold-start speed comparison. All six dossier outputs were nonempty; this alone does not establish factual correctness.
Memory, hardware and cost
Measured on Proxmox VE 9.2.21 / Debian 13, Linux 7.0.14-24-pve, in an LXC guest with isolated Docker inference and scoring. 32 GB installed RAM; the guest was limited to 28 GiB and inference to 26 GiB. Sampled cgroup memory includes cache and is not a peak measurement. GPU capacity is 12 GB; a reliable inference-only peak VRAM figure is not established.
| Model | Sampled RAM range (GiB) | Samples |
|---|
| Flash-Next Coder IQ1_M | 22.57–25.76 | 25 |
| Qwen3.6 UD-Q4_K_XL | 20.51–24.05 | 33 |
| Qwen3.6 UD-Q3_K_M (no MTP) | 16.06–16.21 | 14 |
| Qwen3.6 UD-Q4_K_M (MTP file) | 19.36–25.57 | 14 |
| Qwen3.6 UD-Q3_K_XL (no MTP) | 14.75–17.16 | 13 |
RAM: 2 × 16 GB Corsair CMK32GX4M2E3200C16 at configured 3200 MT/s. Rated 16-20-20-38 at 1.35 V; active timings/voltage unverified. Storage: Intel 1 TB NVMe; benchmark disk expanded from 300 to 400 GiB to retain models and finish the last reference.
Local hardware: $0 rental and $0 quant-creation spend. Electricity, internet, idle-run cost and hardware amortization were not measured; total project cost is unknown.
Use-case routing among the two fully scored models
| Role | Highest rubric score | Score |
|---|
| CFO / Analyst | Qwen3.6 UD-Q4_K_XL | 99.02 |
| Researcher / Scout | Qwen3.6 UD-Q4_K_XL | 98.04 |
| Hermes Coordinator | Qwen3.6 UD-Q4_K_XL | 97.11 |
| Librarian / Knowledge | Qwen3.6 UD-Q4_K_XL | 98.15 |
| Forge / Coder | Flash-Next Coder IQ1_M | 91.92 |
Failures and interpretation limits
- Two models received the full quality suite. Q3_K_M, Q4_K_M and Q3_K_XL received only feasibility, speed and recall tests; their quality is unmeasured here.
- The custom v2.1 applied-task rubric and weighted index are not official Strata quality benchmarks. Official refers to the unmodified upstream speed tool; HumanEval+ is separately scored with EvalPlus.
- HumanEval+ here is one greedy sample per Python task, not a comprehensive software-engineering or end-to-end coding-agent evaluation.
- Coder is a pruned Flash-Next variant; Qwen3.6 is a different model. These are deployment choices, not a controlled quant-only quality comparison.
- Q3 non-MTP compatibility copies add only nextn_predict_layers=0. Original model files are preserved and full tensor-data equality is verified.
- Coder retained one practical transport/engine-stall failure among 72 attempts, and three practical output-limit finishes. Its failure was not replaced with a successful retry.
- MTP requested differs from MTP observed. Qwen3.6 MTP files reported zero drafts offered/accepted in the official measurements; Coder showed active drafts. No on/off ablation was run.
- Official short-chat speed is context-allocation dependent. Compare 32K with 32K and 64K with 64K. Small differences and these few samples do not establish statistical significance.
- A context allocation is distinct from actual exercised prompt length and retrieval validation. Highest tested success is not the exact maximum.
- Three needle positions are a narrow recall test, not a guarantee of all long-context tasks.
- RAM readings are sampled Docker cgroup usage, including counted cache; they are not a measured sustained peak or total PC RAM. VRAM peak is not established.
- The two-client official test used one engine slot and queued requests; it is not two-slot engine concurrency.
- Legacy daily_driver_eligible=false reflects unavailable metadata in the old aggregator; it is not a measured suitability verdict.
- the earlier RTX 5070 Ti system used an RTX 5070 Ti 16 GB, more system RAM, and Strata v0.1.43; do not attribute differences solely to GPU vendor or VRAM.
- RAM rated timings are 16-20-20-38 at 1.35V; active timings and XMP voltage were not verified.
- Dossier timing includes repeated-fixture cache effects. No adaptive-policy timing comparison was run.
IQ3_S and IQ4_XS MTP files failed on unsupported draft-layer formats; IQ3_XXS failed on main-model formats. Genesis-Hermes failed on missing metadata. These were compatibility attempts, not completed benchmarks. Q3 compatibility changes are separately recorded and tensor bytes verified unchanged.
Evidence
Canonical data · Verification · Original official outputs · Official-results PR. Operational archives are private and must not be published. Source links: